GPTBot can't see your JavaScript: the rendering blind spot in AI search
· Technical Guide
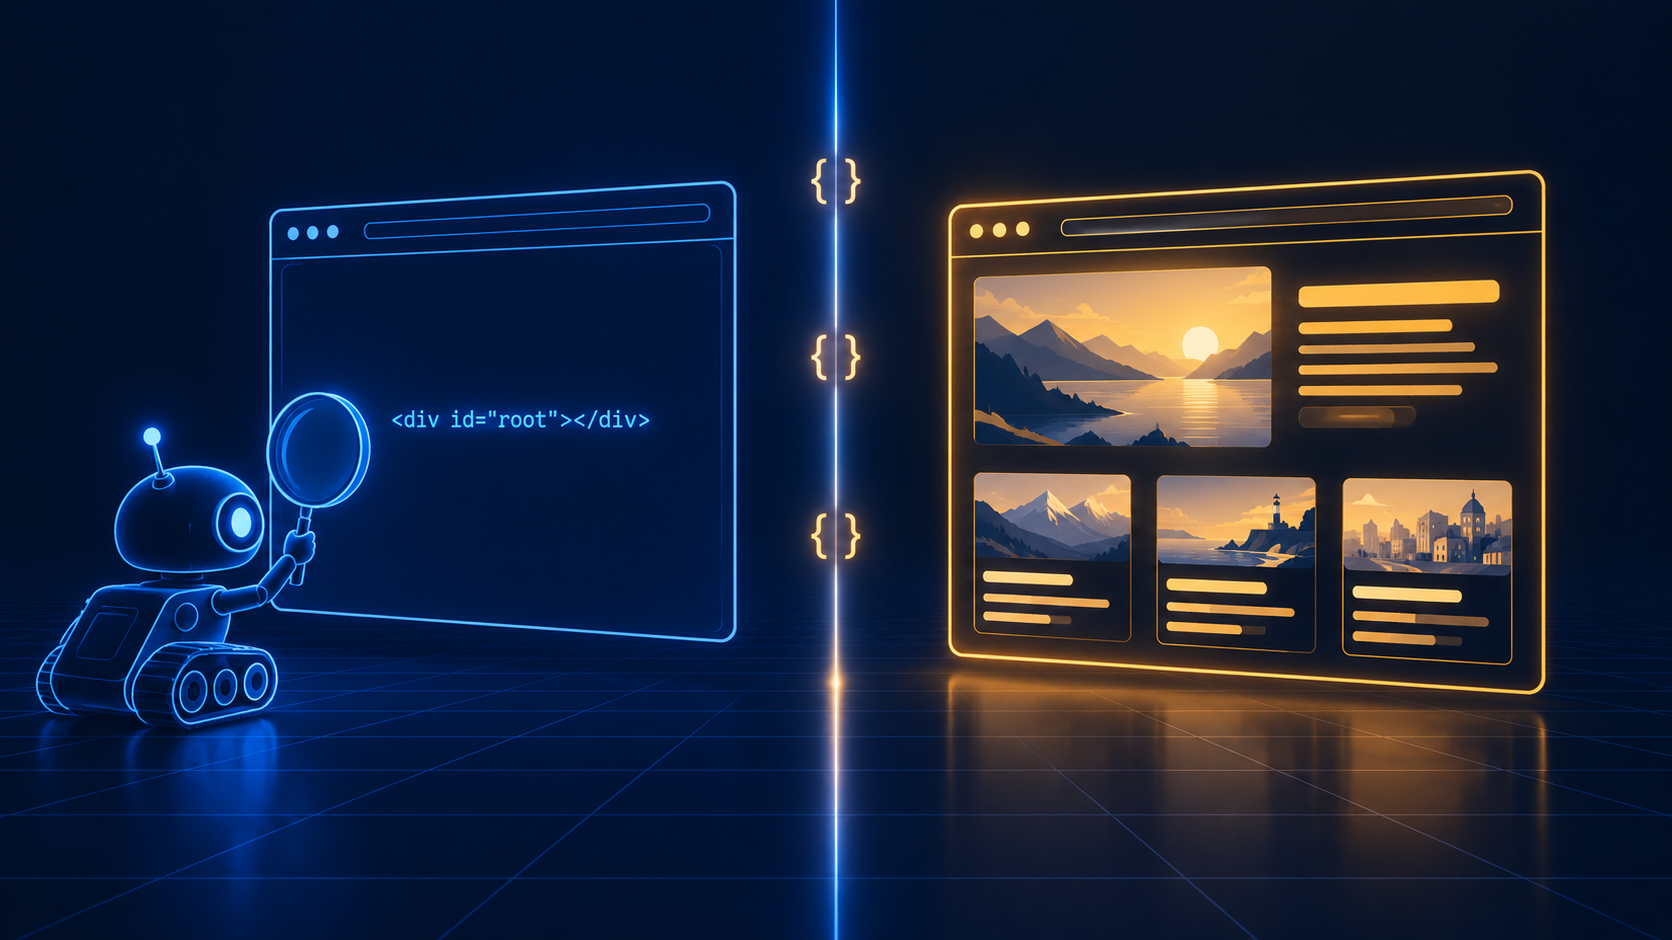
Your page looks perfect in a browser. To the crawler behind the world's most-used AI assistant, it may look like a blank sheet with a single empty div.
There's a quiet assumption behind a lot of AI visibility advice: that if a human can see your content, a machine can too. For Google, that's been broadly true for years, because Googlebot renders JavaScript before indexing. For most of the crawlers that feed AI answers, it isn't true at all.
What the crawlers actually see
Independent testing published this year confirms that GPTBot, ClaudeBot and PerplexityBot still don't execute JavaScript. They fetch the initial HTML your server sends and read that. Anything that only appears after scripts run (product descriptions loaded from an API, article text injected by a front-end framework, FAQ accordions built on the client) simply doesn't exist for them. (Passionfruit)
The exceptions are telling. Google's Gemini and Apple's Applebot see the fully rendered page, because they piggyback on rendering infrastructure their companies built for traditional search. So a JavaScript-heavy site can look healthy in Google's AI Overviews while being close to invisible in ChatGPT, which, according to Previsible's analysis of 166 sites, accounts for about 92% of standalone AI referral traffic (Search Engine Land).
And the stakes are rising. GPTBot traffic is reportedly up 305% year on year. More crawling of pages it can't read doesn't help anyone.
Why this is really a technical-debt story
Carolyn Shelby made a point in Search Engine Land in August that deserves more attention: most of this year's "AI visibility" wins aren't new tactics at all. They're overdue fixes to site architecture, internal linking and rendering, old technical debt finally being repaid because a new class of crawler is less forgiving than Googlebot (Search Engine Land).
Rendering is the clearest example. For a decade, Google's willingness to run JavaScript let teams ship client-rendered sites without much SEO penalty. AI crawlers have removed that safety net. The same is true of how ChatGPT's retrieval stack decides what gets indexed, cached and read before a citation ever appears: if the page it caches is an empty shell, there's nothing to cite (Search Engine Land).
How to check your own site in five minutes
- View source, not the inspector. In your browser, use View Page Source (not DevTools' Elements panel, which shows the rendered DOM). Search for a distinctive sentence from your main content. If it's not in the source, AI crawlers probably can't see it.
- Turn JavaScript off. Disable JavaScript in your browser settings or with an extension, then reload. What's left is roughly what GPTBot reads.
- Fetch it as a crawler would. From a terminal:
curl -s -A "GPTBot" https://yourdomain.com/page | grep "a sentence from your page". No match, no citation. - Check the invisible layers too. Structured data added by a tag manager or a client-side plugin has the same problem. If your JSON-LD is injected by JavaScript, AI crawlers that don't render won't read it.
- Check the pages that matter most: product pages, pricing, key guides and your About page. Templates often differ, and a site can be fine on its blog but empty on its product catalogue.
How to fix it
There's no single right answer. The best fix depends on your stack and your team, but the options, roughly from most to least robust, are:
- Server-side rendering (SSR). The server sends complete HTML on every request; JavaScript then adds interactivity. Most modern frameworks (Next.js, Nuxt, SvelteKit, Remix, Astro) support it natively.
- Static site generation (SSG). Pages are rendered to HTML at build time. Ideal for content that doesn't change per visitor, such as blogs, documentation and marketing pages.
- Pre-rendering for crawlers (dynamic rendering). The server detects crawler user agents and sends them a pre-rendered HTML version, while browsers get the JavaScript app. It's a pragmatic workaround rather than a long-term architecture, and the content must match what users see, or you're into cloaking territory. For transparency: this blog is a single-page React app, and it's exactly how we serve our own posts to AI crawlers.
- Move the critical content into the HTML. If a full re-architecture isn't on the cards, make sure the essentials (headings, the main body copy, key facts, prices and JSON-LD) are in the initial HTML, even if the rest of the experience is client-rendered.
Once your content is readable, make sure crawlers are allowed to fetch it in the first place: robots.txt, your CDN and Google's settings now all have a say, as we explain in Is your site blocking AI search without knowing it? (coming soon). For why server-rendered structured data matters, see From SEO to GEO: why JSON-LD is the hidden layer behind AI visibility.
Frequently asked questions
Can ChatGPT read JavaScript websites? OpenAI's crawlers, like Anthropic's and Perplexity's, read the initial HTML a server returns and don't execute JavaScript. Content that appears only after client-side rendering is unlikely to be seen, indexed or cited.
Does Google's AI Overviews have the same problem? Generally not. Google's Gemini-based features rely on Google's existing rendering infrastructure, which executes JavaScript. That's why a site can appear in AI Overviews while being missing from ChatGPT answers.
What's the quickest way to test if AI crawlers can see my content? View the page source (not the rendered DOM) or disable JavaScript and reload. If your main content isn't there, AI crawlers that don't render JavaScript won't see it either.
Is dynamic rendering considered cloaking? Not if the pre-rendered HTML contains the same content users see. Serving crawlers materially different content is cloaking. Dynamic rendering is a workaround; server-side rendering or static generation are more robust long-term fixes.
The kicker
The web spent fifteen years teaching Google to read JavaScript. The new generation of AI crawlers hasn't bothered to learn, and at the moment they don't need to, because plenty of sites still serve them plain HTML. If yours isn't one of them then it's time to fix it.
Not sure what AI crawlers see on your pages? Run a free CiteSite audit: server-side renderability is one of the six dimensions it scores.
Sources: Passionfruit: JavaScript rendering and AI crawlers, can LLMs read your SPA?; Search Engine Land: AI visibility gains are really technical debt (Carolyn Shelby); Search Engine Land: inside ChatGPT's retrieval stack (Olivier de Segonzac); Search Engine Land: mastering generative engine optimization in 2026 (Previsible data).